Learning under change
Federated optimization and concept-drift adaptation for distributed data that doesn’t stand still.
Explore MASTER-FLResearch Scientist · Amazon
I’m Bhargav Ganguly. I work at the intersection of machine learning, sequential decision-making, and optimization—from theoretical guarantees to systems operating under real-world uncertainty.
Purdue PhD ’24 IIT Kanpur ’19 Bellevue, WA
01 / Research
How can learning systems adapt when data shifts, communication is limited, and decisions have consequences?
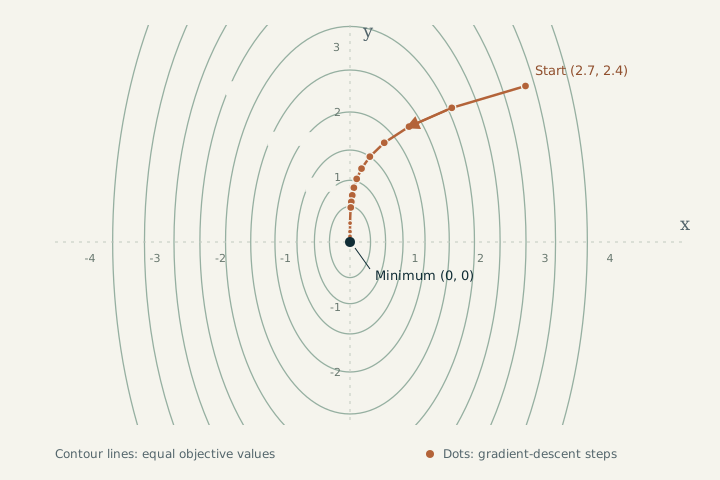
A mathematical lens
Each contour joins points with the same objective value. Each copper dot takes a step against the gradient, approaching the minimum.
Illustrative quadratic objective · θ = (x, y), η = 0.14
A view of optimization, not a result from a paper.
Federated optimization and concept-drift adaptation for distributed data that doesn’t stand still.
Explore MASTER-FLMulti-agent and quantum reinforcement learning, with regret and convergence guarantees.
Explore quantum RLReducing communication in parallel RL and adapting where training and aggregation happen across edge networks.
Explore parallel RL View full-size image
Investigating quantum speedups in exploration through an optimism-driven algorithm and a martingale-free regret analysis.
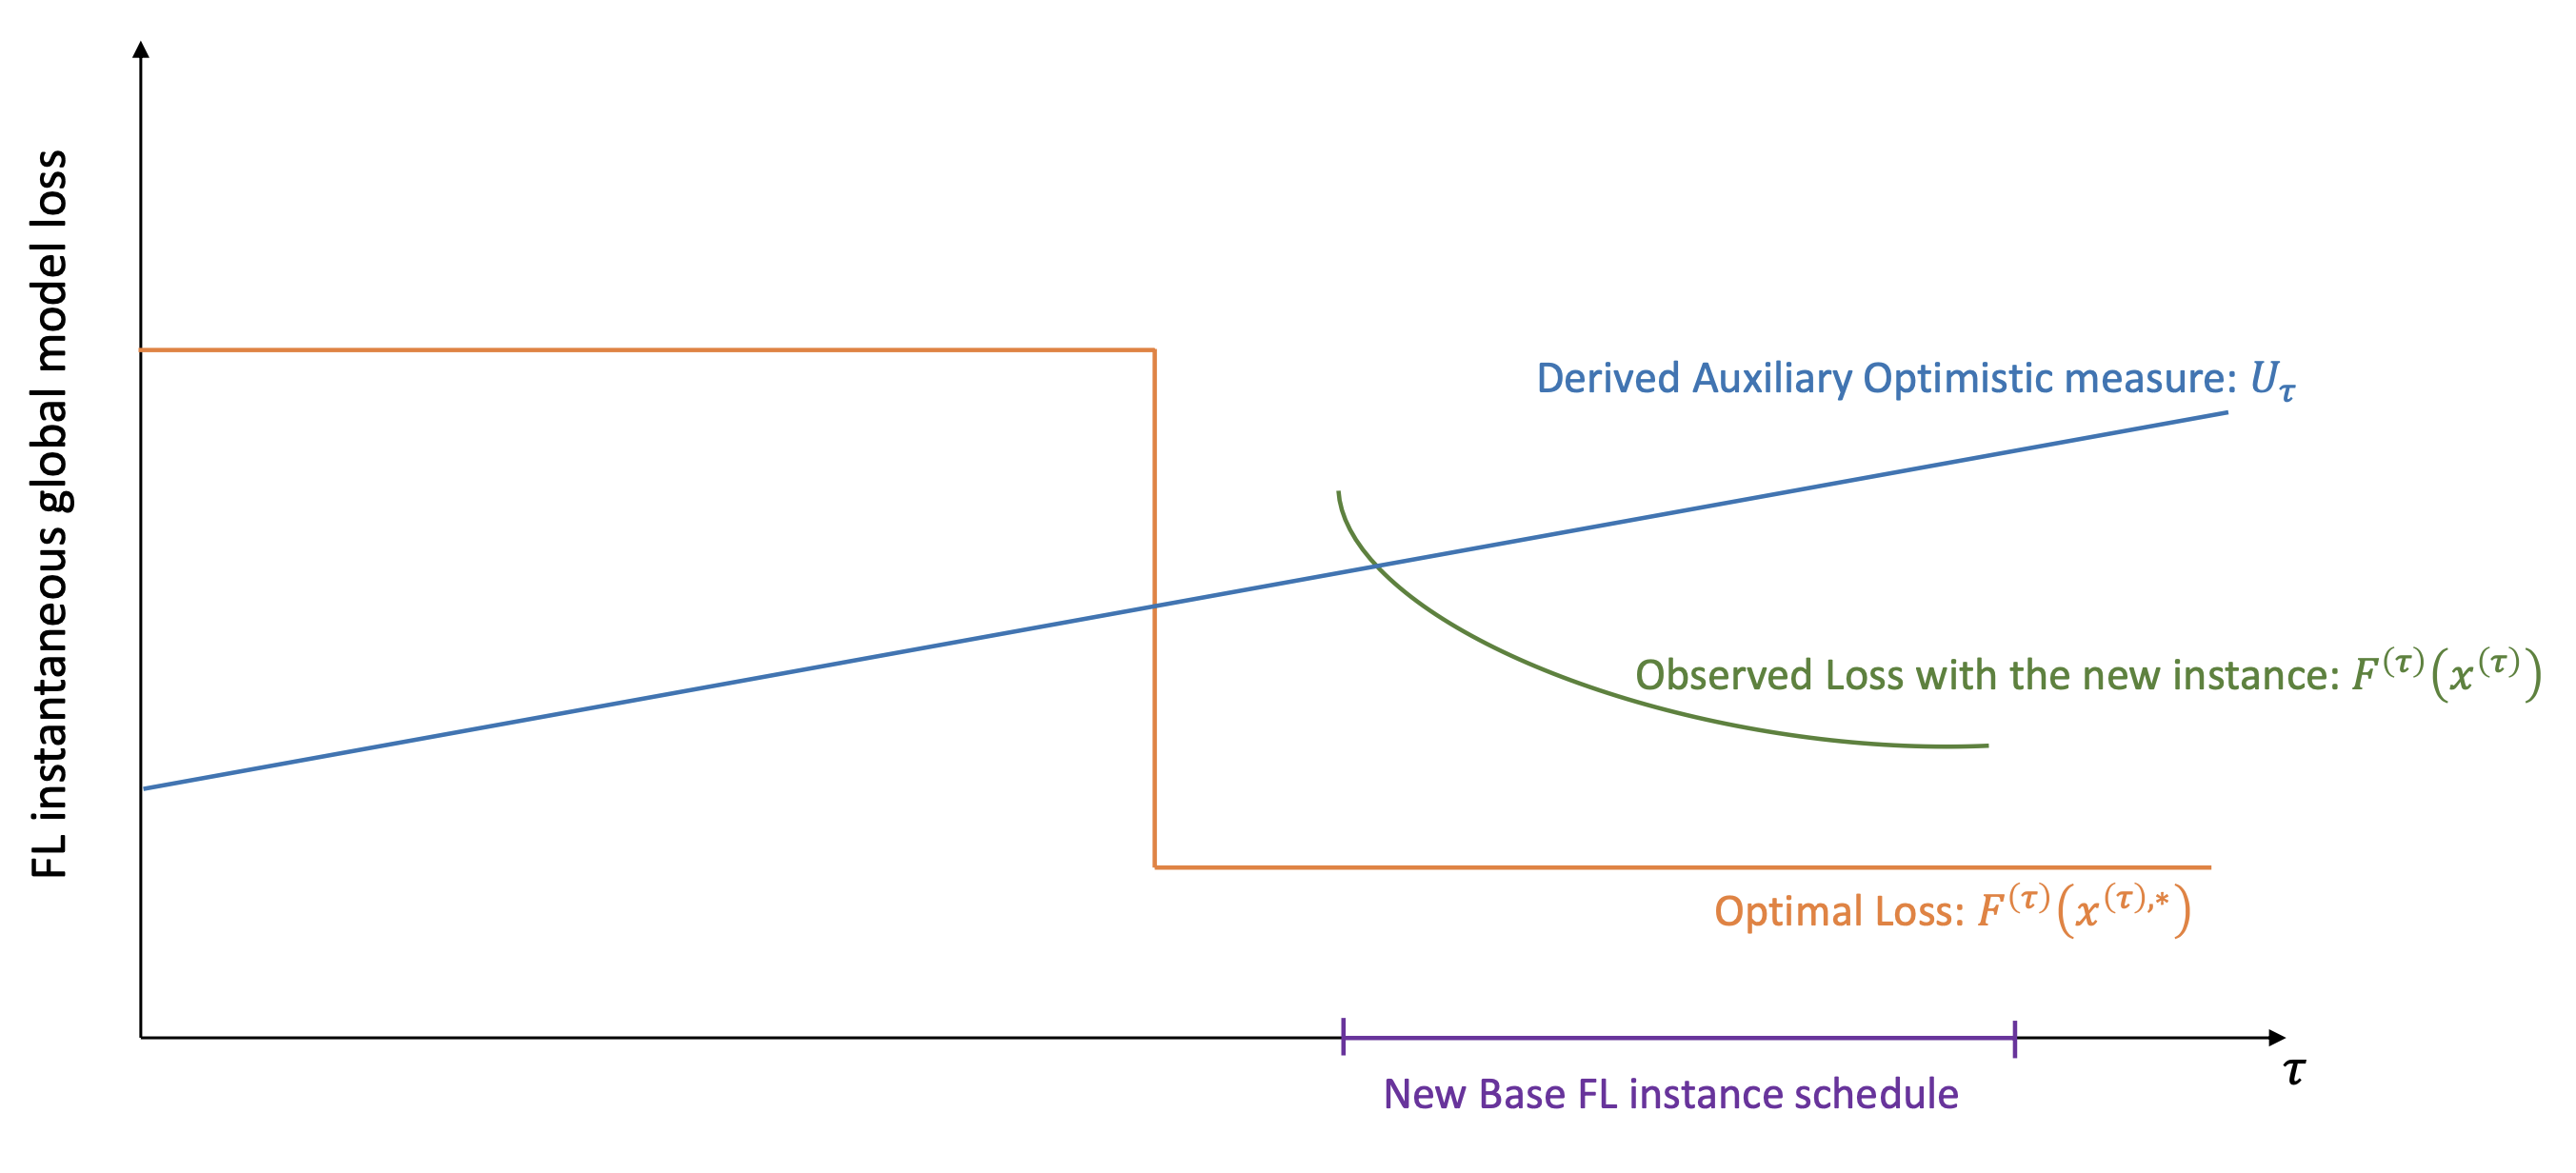 View full-size image
MASTER-FL combines drift detection and multiscale adaptation to establish sublinear dynamic regret guarantees without prior knowledge of drift.
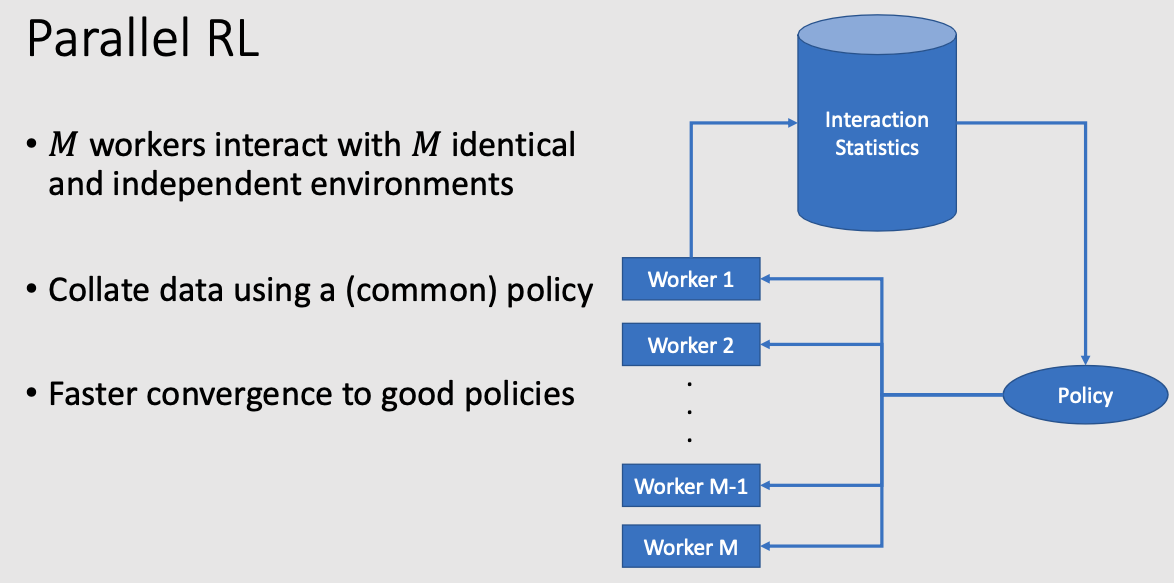 View full-size image
Can parallel agents learn together without constantly exchanging data? DIST-UCRL triggers synchronization using visitation thresholds, with regret guarantees and communication rounds that grow logarithmically with time in the studied tabular setting.
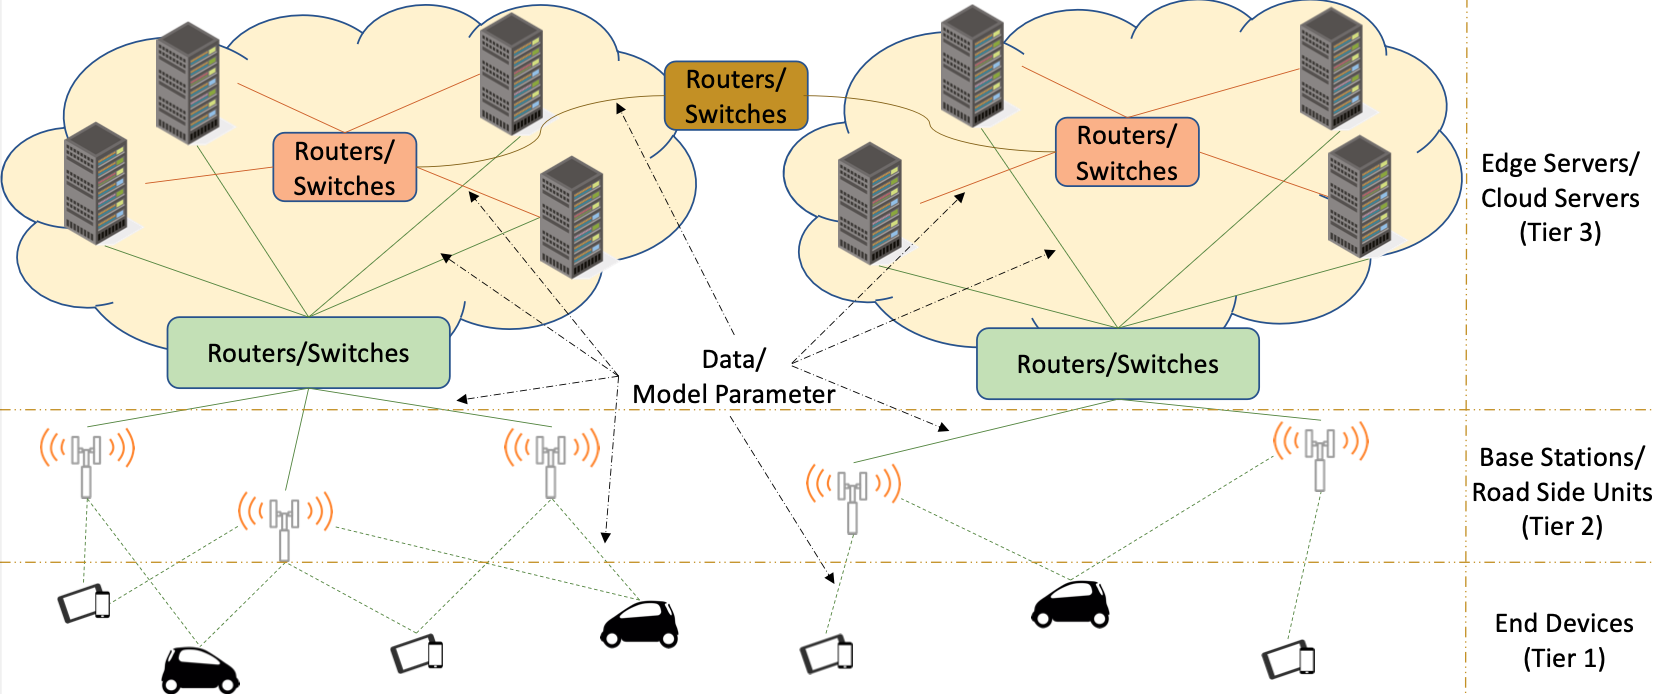 View full-size image
Where should distributed learning happen? CE-FL combines device and edge-server training with data offloading and an aggregation point that can move between rounds, supported by convergence analysis and distributed resource optimization.
A survey of five families of generative models and their roles in offline reinforcement learning and imitation learning.
Human factors, cognitive ergonomics, and the design of AI-enabled mobile computing.
Finite-time convergence and near-global optimality guarantees for decentralized multi-agent RL.
Adaptive exploration and policy learning under abrupt environmental changes.
Decentralized randomized primal-dual methods for average-cost multi-agent learning.
Research notes / Behind the papers
Explanations of the problems, methods, and limits behind my published research.
A visual guide to Q-UCRL: how quantum information changes what an agent can learn, and what its theoretical guarantee actually means.
Read the research note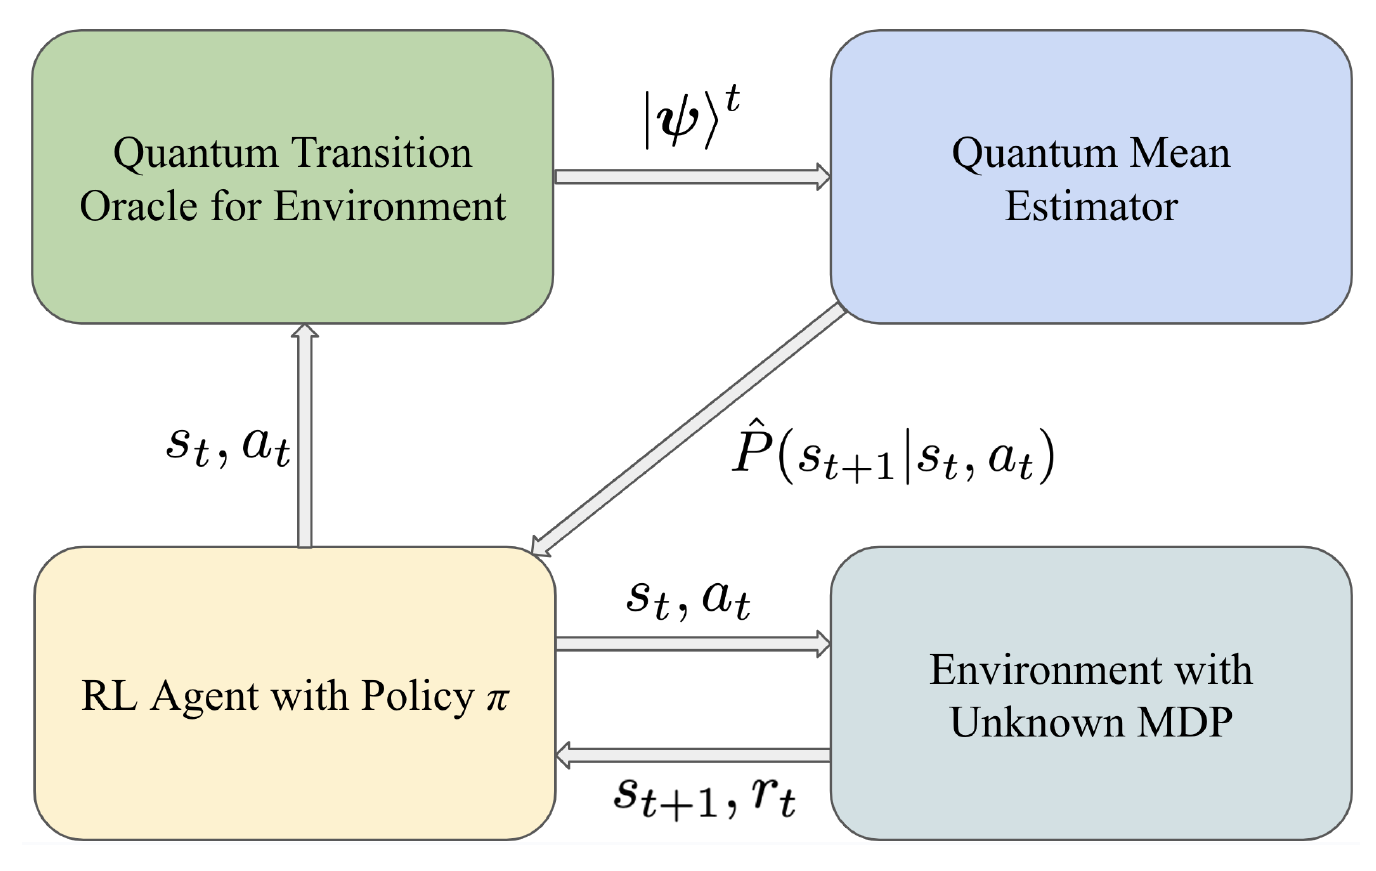
CE-FL shares training across devices and edge servers. See how moving the aggregation point can reduce waiting and energy use.
Read the research note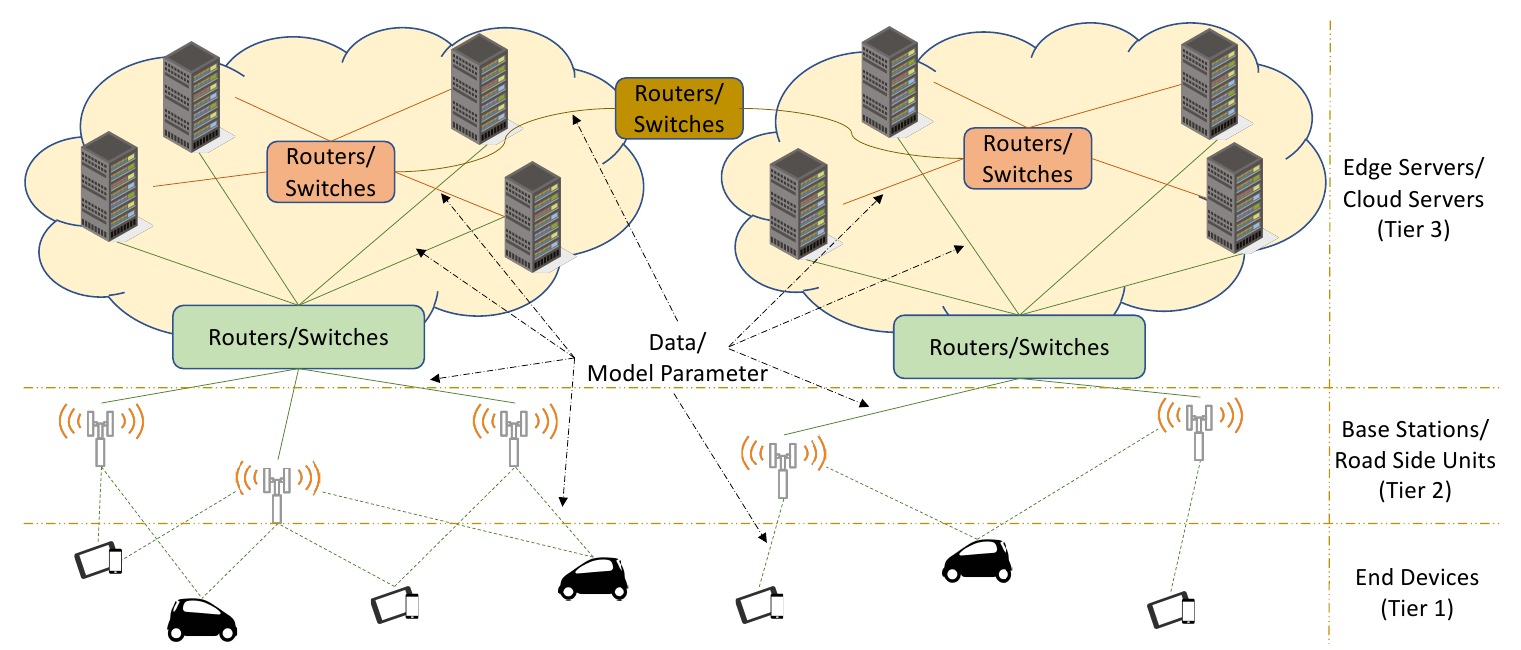
02 / In practice
Research shaped by uncertainty in logistics, distributed learning, and financial systems.
Oct 2024 — Present
Now
Research Scientist · Last Mile Routing & Planning
Bellevue, Washington
Building ML and optimization systems for delivery capacity planning, with a focus on forecasting uncertainty and understanding driver decisions.
May — Aug 2023
Jun — Aug 2022
Research Scientist Intern · Two summers
Bellevue, Washington
Deep reinforcement learning for inventory replenishment, and inference models for vendor behavior.
Jan 2021 — Dec 2024
Research & education
PhD · Industrial Engineering
West Lafayette, Indiana
Federated learning under changing data, decentralized reinforcement learning, and optimization. Graduate research and teaching assistant.
Jul 2019 — Dec 2020
Industry
Quantitative Developer · Wholesale Credit Core Analytics
Mumbai, India
Statistical and ML models to forecast credit losses under economic stress.
May — Jul 2017
During IIT Kanpur
Data Science Intern
Bengaluru, India
Parallel machine learning and cross-validation directly within relational databases.
Jul 2014 — Jun 2019
Education
B.Tech. & M.Tech. · Electrical Engineering
Kanpur, India
B.Tech. 2014–2019 · M.Tech. 2017–2019. Research in compressed online multi-class kernel bandit learning.
03 / Foundations
Industry experience in finance and logistics informs my work on learning algorithms that account for changing data and operational constraints.
Purdue University
Advisor: Prof. Vaneet Aggarwal
Federated Learning Amidst Dynamic Environments ↗Research in online federated optimization, decentralized reinforcement learning, and non-convex optimization under uncertainty.
Indian Institute of Technology Kanpur
Advisor: Prof. Ketan Rajawat
Thesis: Compressed Online Multi-Class Kernel Bandit Learning.
Indian Institute of Technology Kanpur
Graduate Teaching Assistant at Purdue, teaching and mentoring across stochastic modeling, operations research, quality engineering, and predictive analytics.
Program committee and reviewing service includes AAAI, IJCAI, ECAI, ICML, ICLR, and IEEE Transactions on Wireless Communications.
Session Chair, “Coordinated Planning in Complex Transport Networks,” INFORMS Annual Meeting 2025.
04 / Connect
For conversations about AI research roles, scientific collaboration, or the work featured here, connect with me on LinkedIn.